A payment API can accept a charge even when your agent sees a timeout. If the agent sends the request again with a fresh identity, the customer may be charged twice.
AI agent idempotency keys give repeated tool calls a stable identity, so a server can recognize the same intended action. I’d treat them as one layer of write-action safety, not a guarantee against duplicate charges. Durable records, controlled retries, and a way to investigate uncertain outcomes still matter.
Key Takeaways
- Assign one key to each logical write operation, then reuse it across network retries, worker restarts, and agent resumes within one retry budget.
- Keep the operation ID, approved payload, execution state, and provider receipt in durable storage, separate from any audit or action log.
- Use approval gates when an action needs authorization or review. Enforce uniqueness on the server; an agent-generated key is a request for protection, not proof it exists.
- After a post-dispatch timeout, determine whether the action succeeded before creating a new operation.
- Test simultaneous requests and worker crashes. A successful single-threaded retry test misses the hardest failures.
Why Routine Agent Retries Create Duplicate Actions
A chatbot that suggests a refund hasn’t changed a balance. A task invocation that issues a side-effecting tool call can change it. That difference makes ordinary retry logic more consequential.
The Timeout After Success
Imagine an agent sends an external service call to a payment provider to create a charge. The provider commits it, but the response disappears before it reaches the worker. The worker sees a timeout, a failure mode that says nothing conclusive about the charge.
If the worker retries with a new key, the provider may see a new payment request. A model fallback cascade can make matters worse if the replacement model independently decides to call the payment tool again.
The same failure appears with emails, CRM records, ticket creation, and account changes. The issue isn’t that agents are uniquely bad at networking. It’s that an agent loop may turn an ambiguous result into another decision to act.
One Action Can Have Many Attempts
I separate the customer-approved action from each attempt to deliver it. “Charge invoice 481” is one logical operation, even if the HTTP client sends three requests and two workers handle it.
A key created inside a retry callback identifies an attempt. A key created and stored when the business action is approved identifies the operation. Only the second design can reliably connect attempts across process restarts.
How AI Agent Idempotency Keys Should Be Assigned
The model can propose an action. Your application’s action layer should assign its identity, validate arguments, and authorize the write, including state validation before dispatch.
Use Stable Business Intent
I’d give each intended action an operation_id before dispatch. Scope it to a tenant and an action type, such as create_payment or send_invoice_email. Persist the ID with the workflow, so a resumed worker retrieves it rather than generating another.
For multi-step agents, assign separate IDs to separate side effects. Charging an invoice and emailing its receipt need different keys. One key for an entire conversation is too broad; one key for each HTTP attempt is too narrow.
Avoid making the timestamp, retry count, model output, or worker ID part of the operation identity. Those values change during recovery.
Bind the Key to the Approved Payload
Store a request fingerprint of the normalized arguments alongside the operation ID. If an agent retries the same key with a different amount, recipient, or account, reject the request and require a new approval decision.
The fingerprint needs a deliberate schema. Normalize fields that are semantically identical, but don’t erase meaningful changes. For example, changing a payment’s currency must produce a mismatch. Approval should reference that same payload fingerprint.
This rule protects against a subtle failure: a model resumes, revises its tool arguments, and presents a changed action as a retry. For the broader boundary between planning, tools, state, and permissions, see designing reliable AI agent systems.
What Stripe’s Pattern Does and Doesn’t Solve
Stripe’s idempotent requests documentation is a useful model for an external write API. For the API described there, a client supplies an idempotency key with a POST request, and Stripe returns the stored status code and response body for later requests using the same key. That includes a stored 500 response.
Two details matter for agent design. First, the destination server, such as a payment provider, must enforce the key; adding a header in your agent code does nothing by itself. Second, a replayed failure isn’t proof that no side effect occurred. Don’t invent a fresh key to escape an ambiguous response. Inspect the provider’s records and use manual reconciliation to resolve the operation.
An external service call doesn’t make a workflow atomic. A successful charge followed by a failed email still leaves a completed charge and an unsent email. It also doesn’t give you an unlimited retry window. Check the relevant endpoint and API version’s key-retention rules before designing long-running recovery around them.
For a destination without idempotency support, I would require a dependable lookup by external business reference or route uncertain high-risk actions to a person. A local ledger alone can’t guarantee duplicate prevention, because the external system may still accept a second write.
Build a Durable Action Ledger Before Dispatch
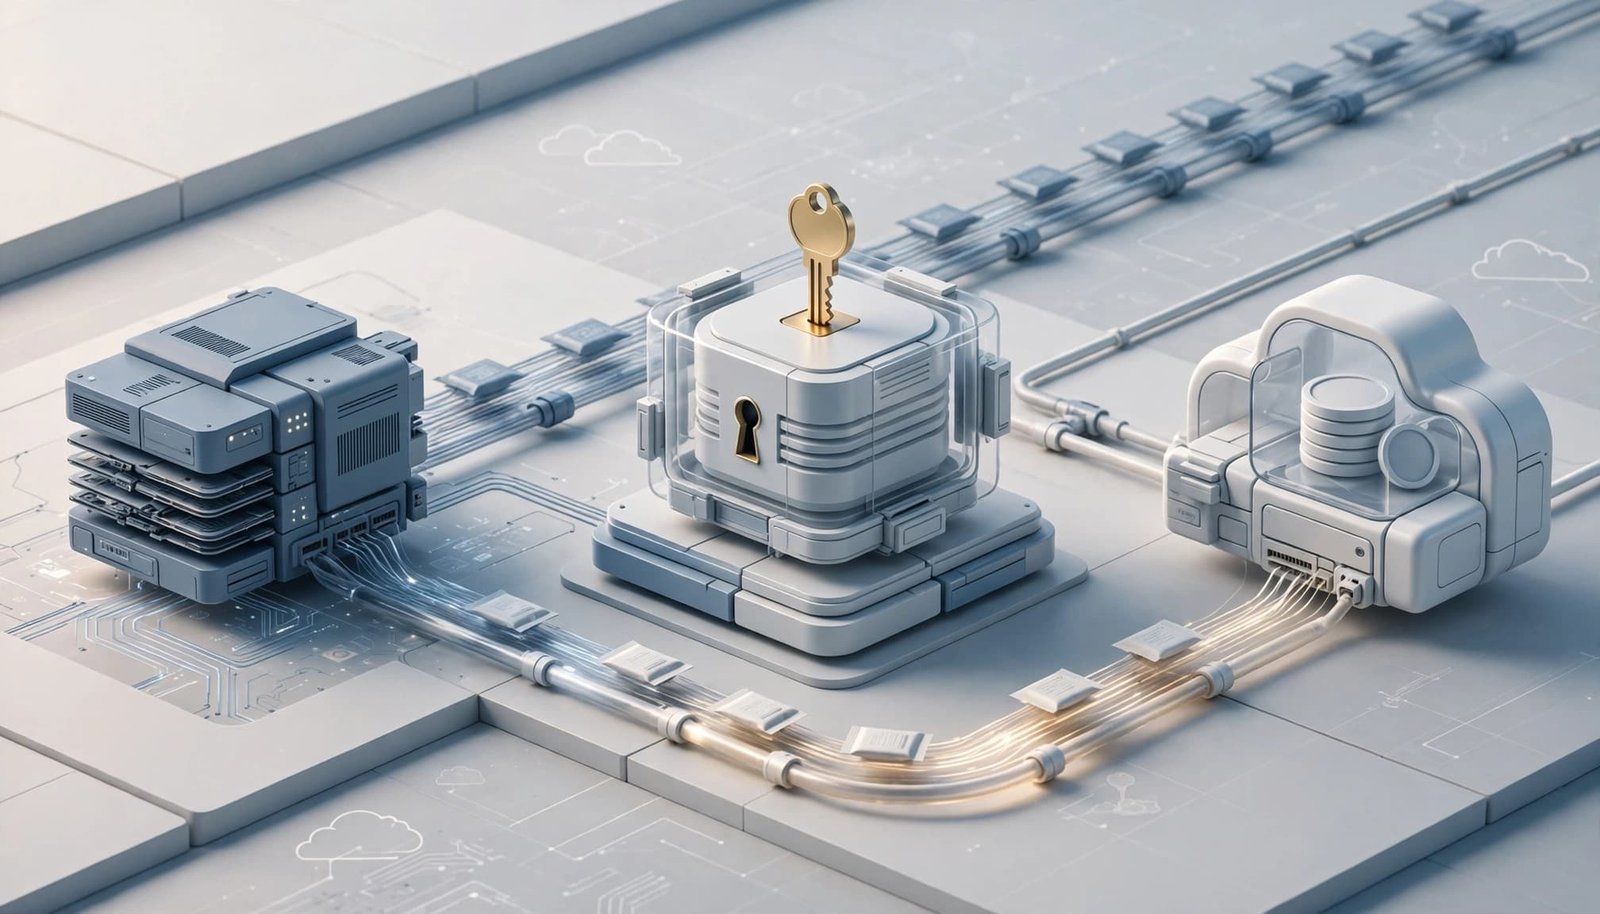
A practical reference architecture doesn’t require a proprietary agent platform. PostgreSQL, a controlled tool gateway, and a worker queue support durable execution across worker and workflow restarts.
Record Intent and Enforce Uniqueness
Create an operations table with tenant_id, operation_id, action_type, payload_hash, status, provider_key, external_reference, attempt_count, and provider_receipt. Add creation and update timestamps, plus a unique constraint on (tenant_id, operation_id).
The gateway’s action layer supports write-action safety by inserting the operation before sending the external request. On a conflict, it loads the existing row and compares payload fingerprints. A match returns the known result or pending status. A mismatch fails without dispatch.
Keep an append-only action log for audit history, separate from the mutable operations table.
I prefer a database constraint over an application-level “check, then insert.” Two workers can both pass that check before either inserts. PostgreSQL’s unique-index documentation describes the database mechanism that should arbitrate the collision.
Keep the Worker Outside the Model’s Authority
After the intent record commits, a worker claims it, rechecks authorization, and sends the approved payload with its stored provider key. The worker then saves the provider receipt and marks the operation confirmed. The agent receives that recorded result.
This division matters when a model repeats itself. The second tool call reaches the gateway, but it can’t create a second operation for the same identity. If you use a framework with checkpoints, persist the operation ID and confirmed result in a database checkpoint too. The operation record remains the durable source of truth. Our AI agent deployment guide covers the wider runtime and recovery choices.
Handle Concurrent Calls Without Trusting a Lock Forever
A unique row prevents duplicate operation records. It doesn’t, by itself, stop two workers from dispatching the same external request.
Claim Work Transactionally
Use a conditional state change so only one worker claims a ready operation. In PostgreSQL, a queue worker can select eligible rows with FOR UPDATE SKIP LOCKED, then commit a short transaction that marks the operation in flight. Don’t hold a database transaction open across a network call.
When a second request arrives while the first is running, return a pending result or wait for the recorded outcome as part of your error handling. Automatic retries shouldn’t open another provider call. A lease can let another worker recover abandoned work, but lease expiry alone doesn’t prove the first worker stopped.
Assume Workers Can Outlive Their Leases
A key failure mode is a paused worker resuming after another worker takes over. If your destination supports idempotency keys, both workers must use the same provider key. Where supported, a fencing token can stop an older worker from updating your local state after its claim expires.
Neither measure makes a destination without duplicate protection safe. For that case, the recovery worker must inspect external evidence before dispatching again. I’d rather leave an operation marked unknown than claim a double charge is impossible because a lock expired correctly.
Recover the Crash Window Standard Checkpoints Miss
Suppose the provider completes an action, then your worker crashes before recording the receipt. Your latest workflow checkpoint still says the step is unfinished. Replaying it as a new action repeats the risk.
Mark Uncertain Outcomes Explicitly
An operation should have states that distinguish ready, in_flight, unknown, confirmed, and rejected. A timeout after dispatch moves it to unknown, unless the provider’s documented key behavior makes a same-key retry safe.
Reconciliation should search the destination using the stored provider key, business reference, or supported correlation reference. If it finds the completed action, save the receipt and resume the agent from that confirmed result. If the evidence remains inconclusive, hold the operation for manual reconciliation.
An empty search result isn’t always proof that a write never happened. The destination may have delayed indexing, limited search, or incomplete metadata.
Preserve Evidence for Operators
Keep an action log separate from the operation record and conversation transcript. It can capture the operation ID, tenant, payload fingerprint, approval record, provider key, attempt history, and any external receipt. Keep sensitive payload data under appropriate access controls.
The question an operator needs answered is concrete: did this exact approved action execute, and what evidence supports that conclusion? A conversation transcript alone can’t answer that. Audit logging for AI agent tool calls covers the trace and approval records that make an investigation possible.
Put Every Retry Layer Under One Budget
An agent can retry at several levels: the HTTP client, tool wrapper, queue worker, workflow runtime, or model. Together, those layers can multiply attempts even when no single layer seems excessive.
Separate Delivery From Decision-Making
A transport retry should repeat the same operation ID, payload, and provider key. A worker retry should recover its durable operation record. A model fallback may explain an error differently, but it must not assign a fresh identity to an already-approved write.
I’d count all these attempts against one run-level retry budget. A fallback doesn’t reset the count. Invalid arguments, denied permissions, and changed payloads need a terminal response or new approval, not another retry.
Slow Down, Then Stop
For transient failures, use bounded exponential backoff with jitter. The AWS SDK retry guidance documents this approach and a retry quota that limits further attempts. It’s a useful transport pattern, but it doesn’t establish whether a timed-out write succeeded.
Circuit breakers can pause calls to a failing dependency across many agent runs. Set limits on attempts, elapsed time, and concurrent work so a provider outage doesn’t become a retry storm. An unknown payment outcome belongs in reconciliation, not an endless retry loop.
Add Approval Gates Where Duplicate Prevention Isn’t Enough
A perfectly deduplicated bad action is still a bad action. Before a write, the action layer should validate the tenant, destination, amount or scope, and caller’s authority. Bind human approval to the exact payload fingerprint being authorized; a later model revision should require another review.
Write-action safety calls for stricter checks around payments, refunds, customer messages, permission changes, and deletion. An internal draft may tolerate automatic recovery. A refund with an uncertain outcome deserves a pause if the provider can’t confirm its status.
Integration platforms and visual automation tools can offer approvals, logs, and retry settings. Those features are useful, but they don’t establish end-to-end write safety. Ask where the operation identity is stored, whether concurrent runs share it, and what happens after an external success followed by a worker crash. If the platform can’t answer those questions, put your own action gateway in front of the write.
Test Repetition, Races, and Crashes
A test should inspect the destination’s state, not just confirm that your gateway returned the same response twice.
Repeat and Race the Same Operation
Send the same approved payload and operation ID repeatedly. Confirm the ledger holds one operation and the destination has one effect. Then submit requests concurrently through separate workers. A unique constraint must settle the race without triggering two dispatches.
Next, reuse the key with a changed amount or recipient. The server should reject it before contacting the provider, and approval gates should require renewed review before any revised operation. Also verify tenant scoping: another tenant must never receive the first tenant’s result. Confirm the retry budget stops attempts at its configured limit.
Inject Failure at the Dangerous Boundaries
Kill a worker after it commits intent but before dispatch. Kill it again after the destination accepts the write but before the local receipt commits. Drop the provider response and resume the workflow on another worker.
For each case, check the ledger state, action log, provider record, attempt count, and agent-visible result. A recovered agent should consume a confirmed receipt, wait on an unknown outcome, or request review. It shouldn’t reason its way into a fresh write.
Track unknown-operation age and reconciliation time in production. A growing unknown queue tells you more about write safety than a dashboard of successful agent answers.
Frequently Asked Questions
Can an AI Agent Generate Its Own Idempotency Key?
It can produce a string, but I wouldn’t let the model define operation identity. The application should assign or retrieve a durable ID when an action is authorized, with approval gates tied to that record. The model’s tool call then passes through a gateway that checks the stored action and payload.
Do Idempotency Keys Guarantee Exactly-Once Execution?
No. A key can help a destination deduplicate requests for one defined operation. It doesn’t make separate services participate in one atomic transaction, and it can’t repair an unsupported destination. Recovery still needs receipts, reconciliation, or a human decision.
Should a New Agent Run Reuse an Old Key?
Reuse it when the run is resuming the same approved action within the destination’s supported rules. A genuinely new action needs a new operation ID, even if its arguments look similar. Business identifiers and approval records should make that distinction explicit.
What Happens if the Provider Returns a 500?
Follow that provider’s documented behavior. Stripe’s documented API pattern can replay the first result for a key, including a 500. Treat the outcome as uncertain until provider records establish what happened. Creating a fresh key merely to obtain a different response can create a second action.
Where to Go Deeper
Three related engineering questions deserve their own treatment:
- How should PostgreSQL leases, worker claims, and fencing tokens behave under heavy contention?
- Which payment, email, and CRM APIs support provider-side deduplication, and how long do they retain keys?
- How can a crash-injection test harness prove that an agent resumes without repeating external writes?
Final Thoughts
The timeout in the opening example isn’t a reason to charge the customer again. It’s a reason to find out what the first request did.
For write-action safety, I’d give each approved action one durable identity, enforce it at the gateway, and carry it to the destination. Unknown stays unknown until a receipt or reconciliation resolves it.