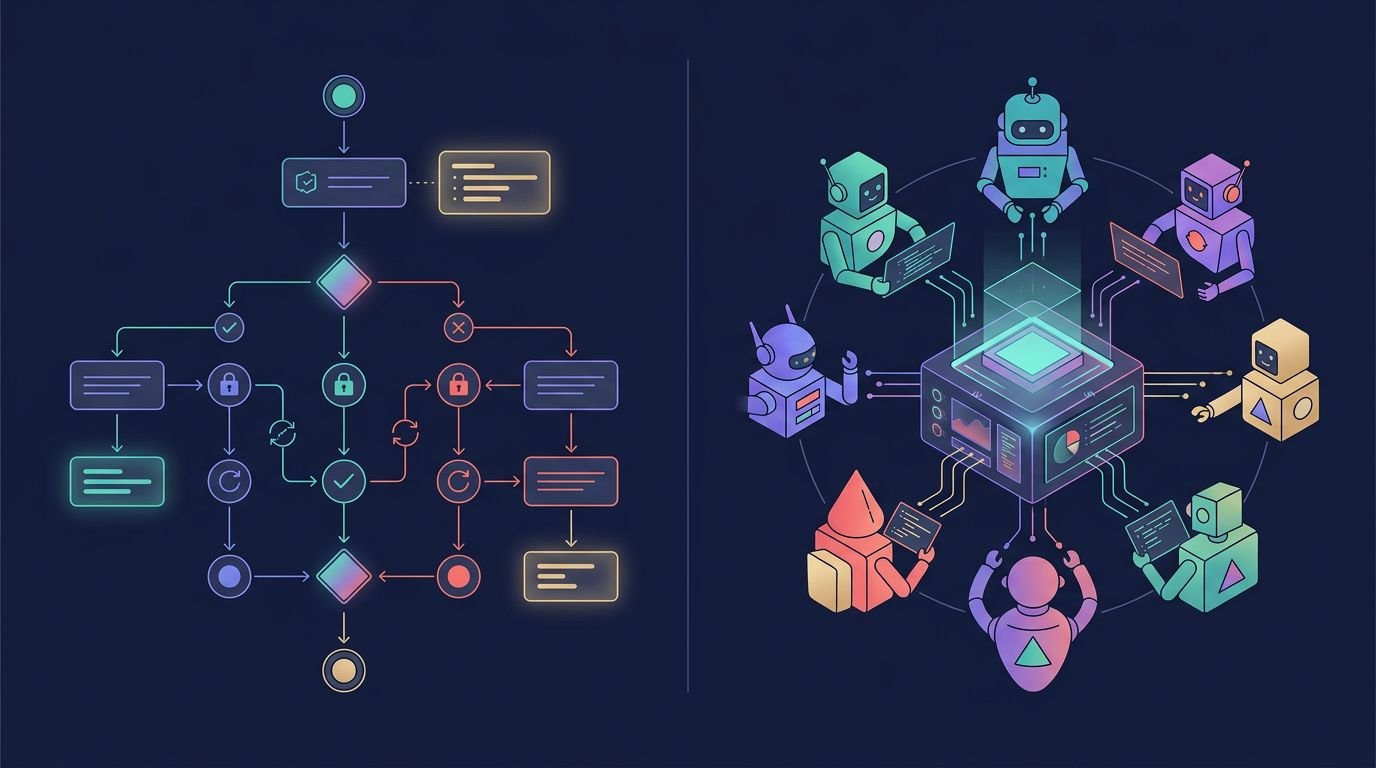
LangGraph vs CrewAI for small SaaS teams: which fits?
AI agents rarely fail because they cannot produce an answer. Production failures usually happen around tool timeouts, customer approvals, blocked permissions, and lost context. LangGraph
AI agents rarely fail because they cannot produce an answer. Production failures usually happen around tool timeouts, customer approvals, blocked permissions, and lost context. LangGraph
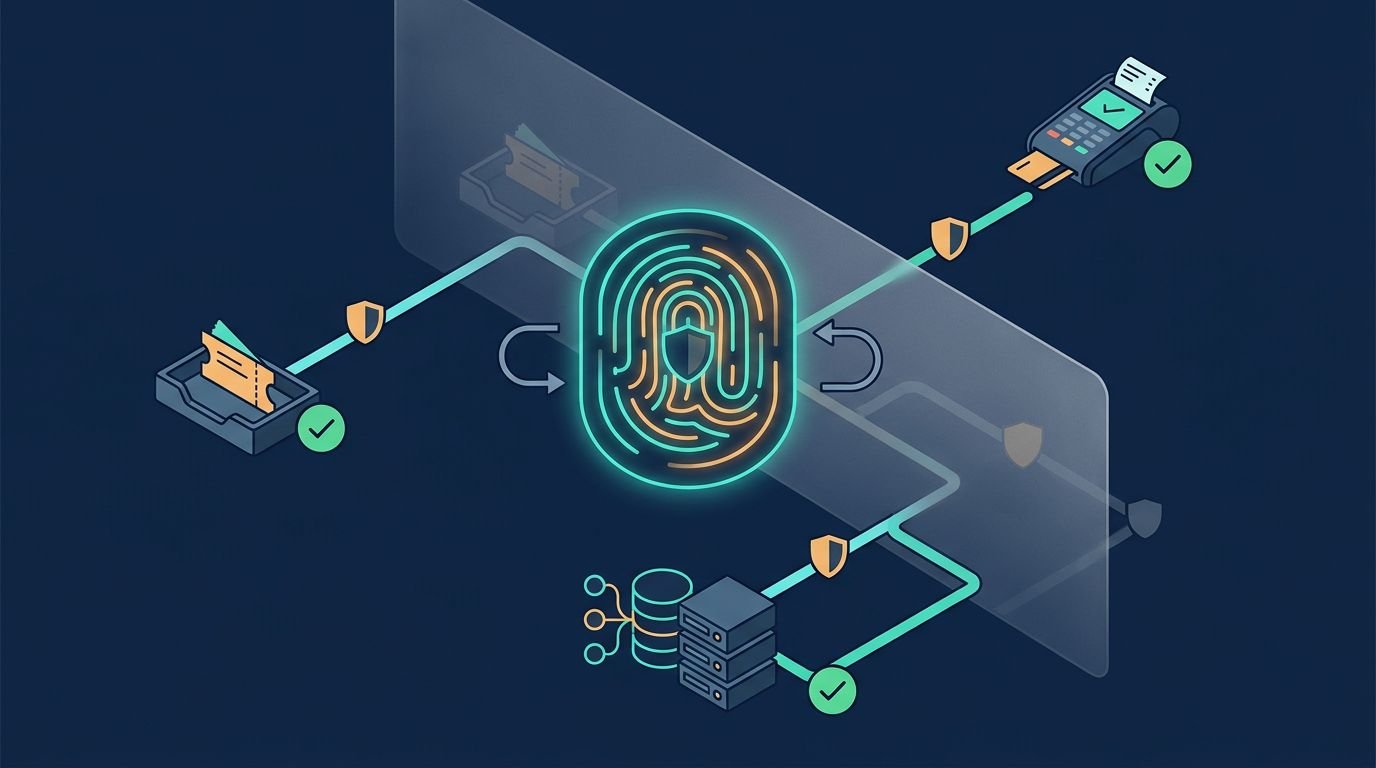
During a multi-turn conversation, a retry can turn a timeout into a duplicate payment, second support ticket, or overwritten customer record. When I review production
An agent with unrestricted tool access can turn one bad inference into a real operational problem. Human approval AI agents reduce that exposure by stopping

An answer can match a question perfectly and still quote a policy that stopped applying yesterday. Retrieval-augmented generation can return semantically relevant evidence while ignoring

Disclosure: This is a sponsored review, but my testing, observations, criticism, and final recommendation reflect my honest opinion. Managing several Android accounts, testing mobile apps
Contracts rarely cause problems on signature day. Trouble usually appears later, when a renewal date passes, a customer asks what was promised, or a vendor’s
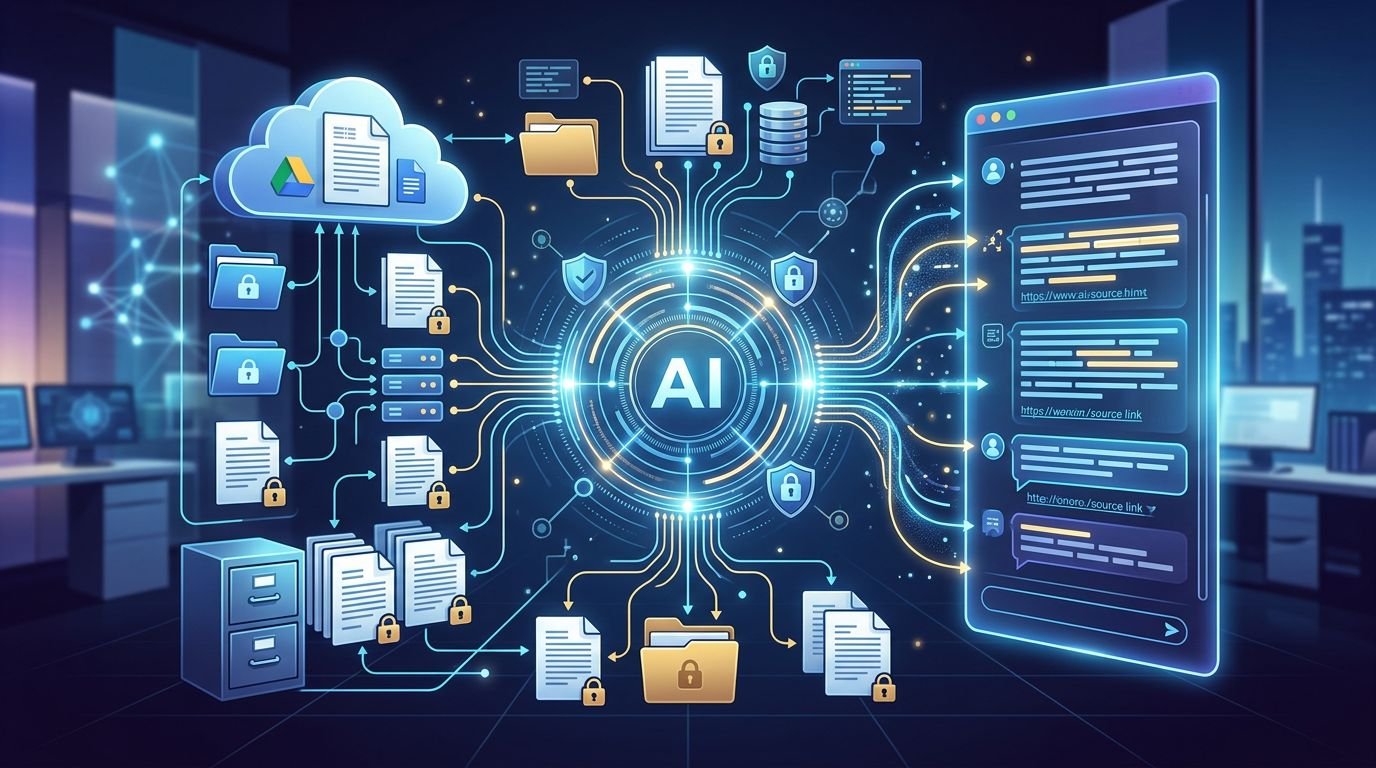
Your files are only useful to a chatbot when it can find the right passage, honor the reader’s access, and show its work. This assistant
A small app can create unnecessary spend for large language models when it sends the same 2,000-token context hundreds of times each day. LLM caching
A chatbot can attach a neat “[1]” to every answer and still point users to the wrong evidence. Unsupported citations weaken user trust, because a
In retrieval augmented generation (RAG) architectures powered by large language models, a chatbot can give a perfect answer and still create a serious security incident.